Azure OpenAI is bring-your-own-key only. Pullfrog never proxies Azure traffic.
Setup
1
Store the five values
In the Pullfrog console, click Set up on the Azure OpenAI tile of the Providers card and fill in the five values from the table below. Pullfrog injects them into every run, so 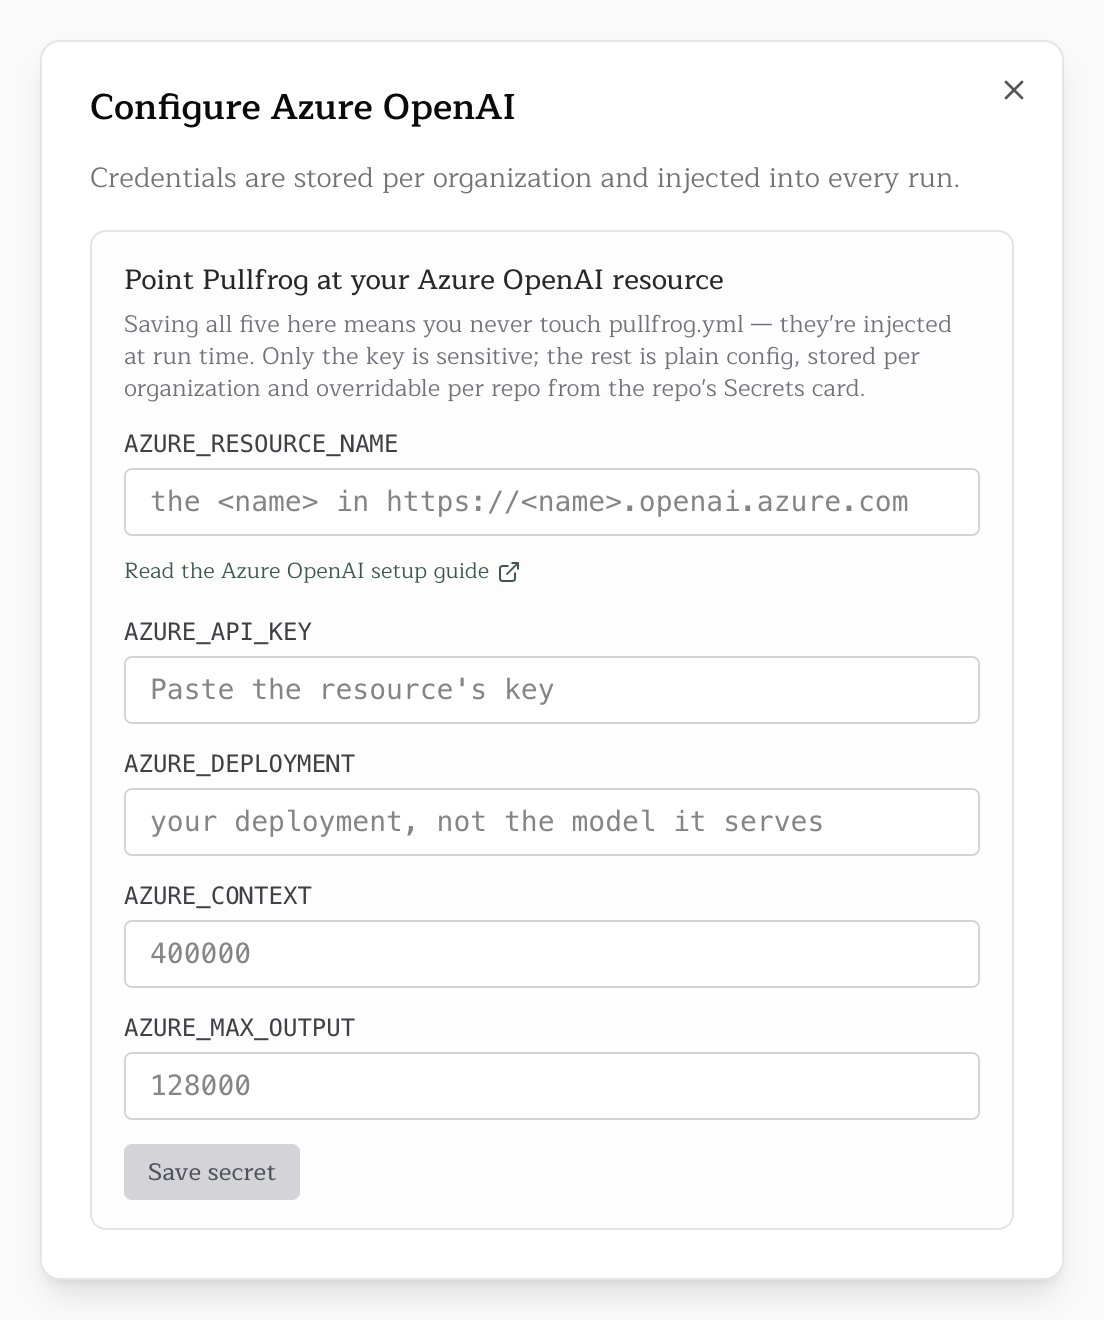
pullfrog.yml needs no changes.AZURE_API_KEY in a GitHub Actions secret and the rest in the env: block of .github/workflows/pullfrog.yml:2
Pick the model
On the Model card, choose Manual and pick Azure OpenAI from the model menu.
Variables
The first five are required. The two limits must be positive numbers, so
128k is rejected. A value set in the workflow wins over a stored one.
On an account that pays through Pullfrog Router, store the values in the Pullfrog console. Pullfrog decides how to fund a run before the runner starts, when GitHub Actions secrets are not visible to it, so a run whose key exists only there falls back to the Router’s default model.
Token limits
A deployment name carries no model metadata, so Pullfrog cannot look up the limits and needs you to declare them. Undeclared limits would break two things:- Completions are capped at 32000 tokens, and a model with a smaller cap rejects every request.
- Auto-compaction turns off. Compaction keys off the context limit, so a long session grows until Azure refuses it.
AZURE_CONTEXT to the real window of the deployed model. A low value compacts earlier than needed; a high value delays compaction until Azure refuses the request.
Reasoning effort
The effort setting does not apply to Azure runs. A deployment name does not identify a model, so Pullfrog sends no effort level and the model’s own default applies.Deployment name
Azure routes on the deployment name, not the model name. SetAZURE_DEPLOYMENT to the name given to the deployment, which defaults to the model’s name but is often changed:
- Deployed
gpt-5and kept the default name:AZURE_DEPLOYMENT: gpt-5 - Renamed the deployment
prod-reasoning:AZURE_DEPLOYMENT: prod-reasoning
Routing
Pullfrog sends requests to the resource’s Responses endpoint,/openai/v1/responses, through OpenCode’s azure provider. GPT-5-family models speak it as deployed. Older deployments such as gpt-4 and gpt-35-turbo speak only Chat Completions; set AZURE_USE_CHAT_COMPLETIONS: "true" for them.
Pullfrog sends a static key and cannot refresh a Microsoft Entra ID token during a run. If your organization forbids resource keys, put a gateway that does the token exchange in front of the resource, and point OpenAI-compatible endpoints at the gateway.