> ## Documentation Index
> Fetch the complete documentation index at: https://docs.pullfrog.com/llms.txt
> Use this file to discover all available pages before exploring further.
# OpenAI-compatible endpoints
> Run Pullfrog against any endpoint that speaks the OpenAI Chat Completions API, such as LiteLLM, Cloudflare AI Gateway or vLLM.
Route Pullfrog's model calls to any endpoint that speaks the OpenAI Chat Completions API: a [LiteLLM](https://docs.litellm.ai/docs/simple_proxy) proxy, [Cloudflare AI Gateway](https://developers.cloudflare.com/ai-gateway/), [Alibaba DashScope](https://www.alibabacloud.com/help/en/model-studio/), or a self-hosted [vLLM](https://docs.vllm.ai/) server. Use it for a model the catalog does not carry, several providers behind one gateway, or your own inference.
A provider listed on [models.dev](https://models.dev) runs from its own API key, with no base URL or token limits to declare; see [custom providers](/models#custom-providers). For Azure OpenAI, use [Azure OpenAI](/azure) instead.
OpenAI-compatible endpoints are bring-your-own-key only. Your provider bills inference to your account, and Pullfrog never proxies this traffic.
## Setup
In the Pullfrog console, pick the **Custom (OAI)** tile on the **Provider** card.
Click **Set up** on the tile and fill in the five values from the table below. Pullfrog injects them into every run, so `pullfrog.yml` needs no changes. Values stored for the organization can be overridden per repository.
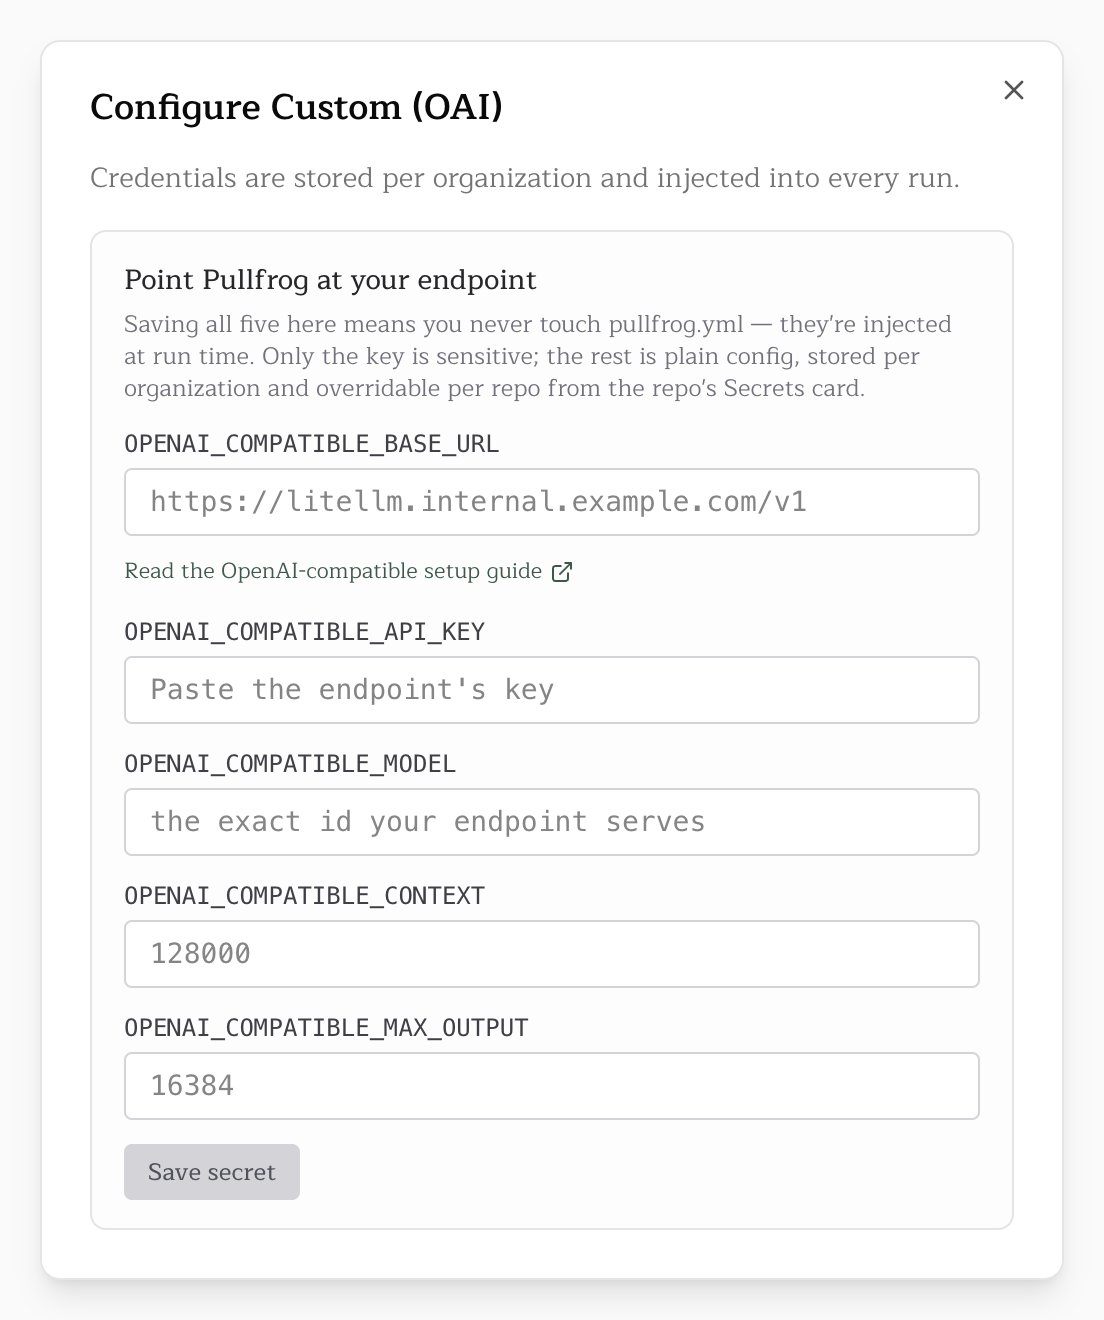 To keep them in the workflow instead, put `OPENAI_COMPATIBLE_API_KEY` in a GitHub Actions secret and the rest in the `env:` block of `.github/workflows/pullfrog.yml`:
```yaml theme={null}
env:
OPENAI_COMPATIBLE_BASE_URL: https://gateway.ai.cloudflare.com/v1///compat
OPENAI_COMPATIBLE_API_KEY: ${{ secrets.OPENAI_COMPATIBLE_API_KEY }}
OPENAI_COMPATIBLE_MODEL: workers-ai/@cf/meta/llama-3.1-8b-instruct
OPENAI_COMPATIBLE_CONTEXT: "128000"
OPENAI_COMPATIBLE_MAX_OUTPUT: "16384"
```
## Variables
| Name | Secret | Purpose |
| - | - | - |
| `OPENAI_COMPATIBLE_BASE_URL` | No | Base URL of the endpoint, the path that serves `/chat/completions`. |
| `OPENAI_COMPATIBLE_API_KEY` | Yes | API key or bearer token for the endpoint. |
| `OPENAI_COMPATIBLE_MODEL` | No | Exact model ID the endpoint serves. Pullfrog runs it as written and never upgrades it. |
| `OPENAI_COMPATIBLE_CONTEXT` | No | Context window of that model, in tokens. |
| `OPENAI_COMPATIBLE_MAX_OUTPUT` | No | Maximum completion tokens that model accepts. |
All five are required, and a run without them fails before the agent starts. The two limits must be positive numbers, so `128k` is rejected. A value set in the workflow wins over a stored one.
Put the key only in `OPENAI_COMPATIBLE_API_KEY`, never inside the base URL. A base URL set in the workflow is not masked in logs.
On an account that pays through [Pullfrog Router](/billing#pullfrog-router), store the values in the Pullfrog console. Pullfrog decides how to fund a run before the runner starts, when GitHub Actions secrets are not visible to it, so a run whose values exist only there falls back to the Router's default model.
### Token limits
Your endpoint owns the model catalog, so Pullfrog cannot look up the model's limits and needs you to declare them. Undeclared limits would break two things:
* **Completions are capped at 32000 tokens**, and a model with a smaller cap rejects every request. GPT-4o and GPT-4o mini stop at 16384, and many open models at 4096 or 8192.
* **Auto-compaction turns off.** Compaction keys off the context limit, so a long session grows until the endpoint refuses it.
Set `OPENAI_COMPATIBLE_CONTEXT` to the model's real window. A low value compacts earlier than needed; a high value delays compaction until the endpoint refuses the request.
## Model IDs
The model menu has a single **OpenAI-compatible** entry; `OPENAI_COMPATIBLE_MODEL` names the actual model, in your gateway's own format:
| Gateway | Model ID format | Example |
| - | - | - |
| [Cloudflare AI Gateway](https://developers.cloudflare.com/ai-gateway/usage/chat-completion/) | `/` | `workers-ai/@cf/meta/llama-3.1-8b-instruct` |
| DashScope | Bare model ID | `qwen3-coder-plus` |
| LiteLLM proxy | The `model_name` from the proxy's `model_list` | `claude-opus-internal` |
### LiteLLM
A [LiteLLM proxy](https://docs.litellm.ai/docs/simple_proxy) needs no special configuration. Point the base URL at the proxy's `/v1` path and use a [virtual key](https://docs.litellm.ai/docs/proxy/virtual_keys):
```yaml theme={null}
env:
OPENAI_COMPATIBLE_BASE_URL: https://litellm.internal.example.com/v1
OPENAI_COMPATIBLE_API_KEY: ${{ secrets.LITELLM_VIRTUAL_KEY }}
OPENAI_COMPATIBLE_MODEL: claude-opus-internal # model_name from model_list
OPENAI_COMPATIBLE_CONTEXT: "200000"
OPENAI_COMPATIBLE_MAX_OUTPUT: "32000"
```
LiteLLM's own routing, failover and spend tracking apply as configured. The same setup covers models the proxy serves from self-hosted vLLM or Ollama.
## Routing
Pullfrog runs the model on OpenCode, through an [`@ai-sdk/openai-compatible`](https://www.npmjs.com/package/@ai-sdk/openai-compatible) provider pointed at `OPENAI_COMPATIBLE_BASE_URL`. Requests go to `/chat/completions` with your key as the bearer token.
## Troubleshooting
| Symptom | Fix |
| - | - |
| `OPENAI_COMPATIBLE_MODEL env var is required when the model is set to "openai-compatible/byok"` | The repository uses the OpenAI-compatible entry, but no model ID is stored or set in the workflow. |
| "OpenAI-compatible model selected but required configuration is missing" | The message names each missing or non-numeric value. |
| `max_tokens is too large` | The value of `OPENAI_COMPATIBLE_MAX_OUTPUT` is above what the model accepts. Lower it to the model's real limit. |
| HTTP `404` from the endpoint | Pullfrog appends `/chat/completions` to the base URL, so the base URL is usually the path that ends in `/v1`. |
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.