> ## Documentation Index
> Fetch the complete documentation index at: https://docs.pullfrog.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Models
> Pick a model per repository or let Smart pick one per pull request, and see how Pullfrog resolves the model and agent a run uses.
Pullfrog model names are rolling aliases, like a `latest` tag on npm. "Claude Opus" resolves to a concrete version at runtime (`anthropic/claude-opus-5-5`), and when a new generation ships the alias moves with it. Your configuration doesn't change.
## Selecting a model
Pick a provider and a model in the **Agent** section of the repository [console](https://pullfrog.com/console). Set an organization default in the **Model** section of the org console; every repository inherits it until it picks its own.
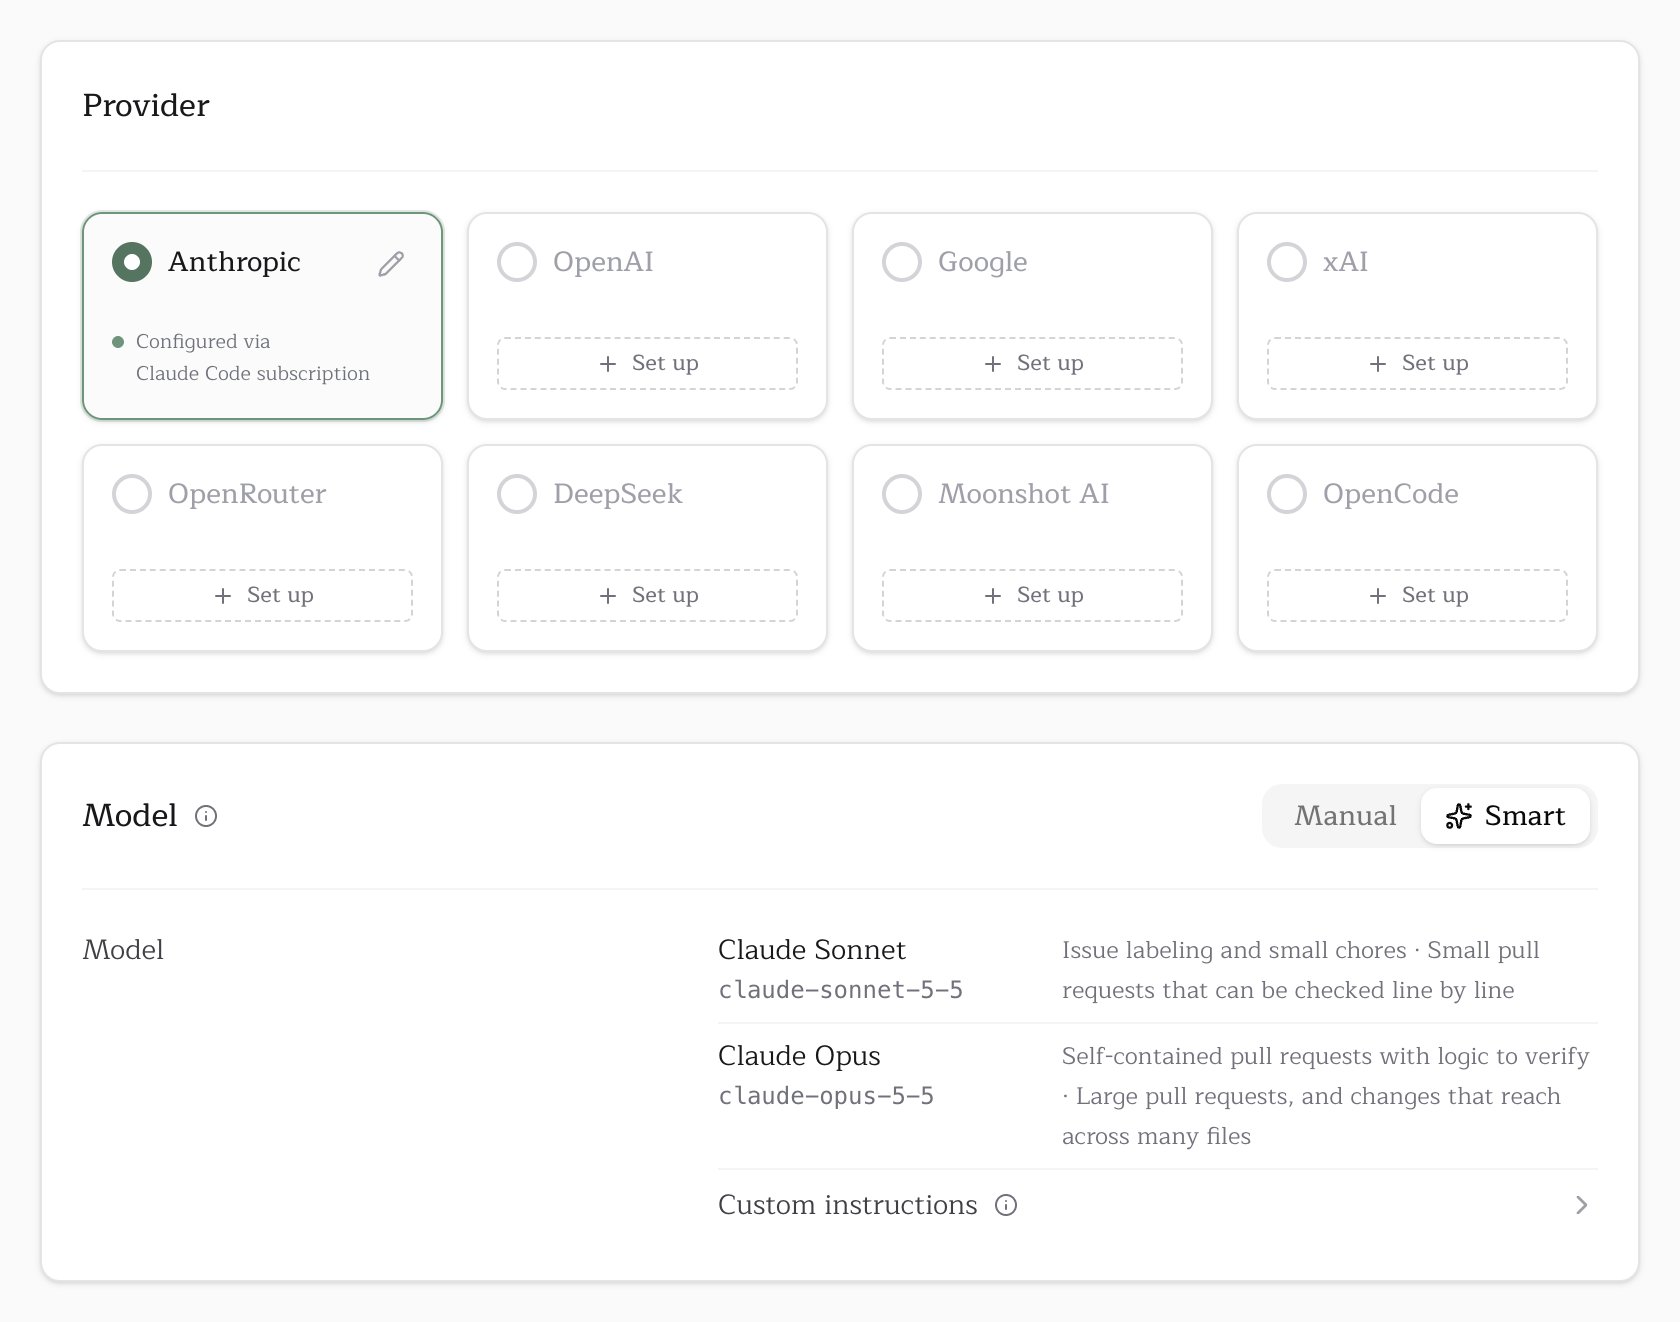 The **Provider** card shows each provider with the credential that pays for it, or a way to set one up. The **Model** card has two tabs:
| Tab | What it does |
| - | - |
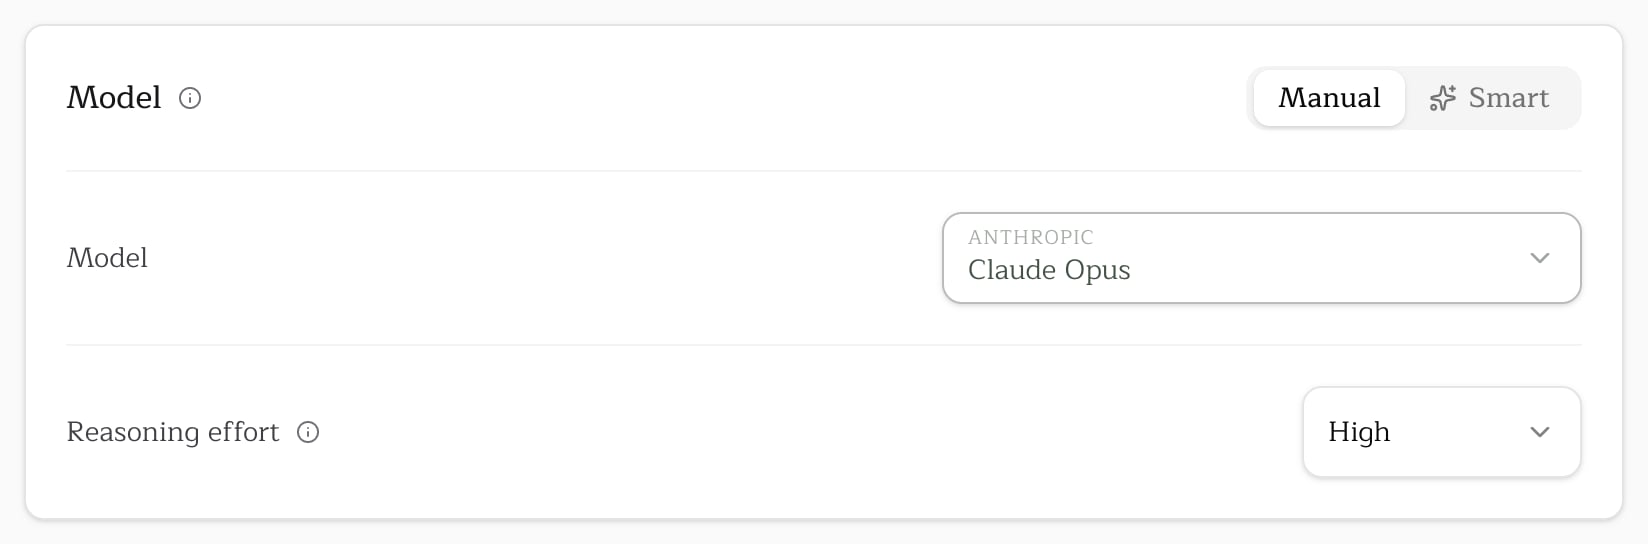
| **Manual** | Pins one model from the provider's menu, with its reasoning effort |
| **Smart** | Picks a model from the provider's ladder for each piece of work. See [Smart](#smart). |
Models marked **Free** cost nothing per token but still need an `OPENCODE_API_KEY`. See [free models](/model-access#free-models).
On [Pullfrog Router](/billing#pullfrog-router) without a card on file, a positive balance runs DeepSeek Flash and every other model is locked. With no balance and no card, Router runs stop. Free models, models you hold a [Pullfrog-stored key](/keys) for, and BYOK accounts are not affected.
## Reasoning effort
Under a pinned model, **Reasoning effort** offers the levels that model publishes. Pullfrog stores the setting as a position on the model's range, so it keeps its place when you switch models. Smart sets effort for each run itself. To override effort for a single run, use the [`--effort` flag](/flags#effort).
 ## Smart
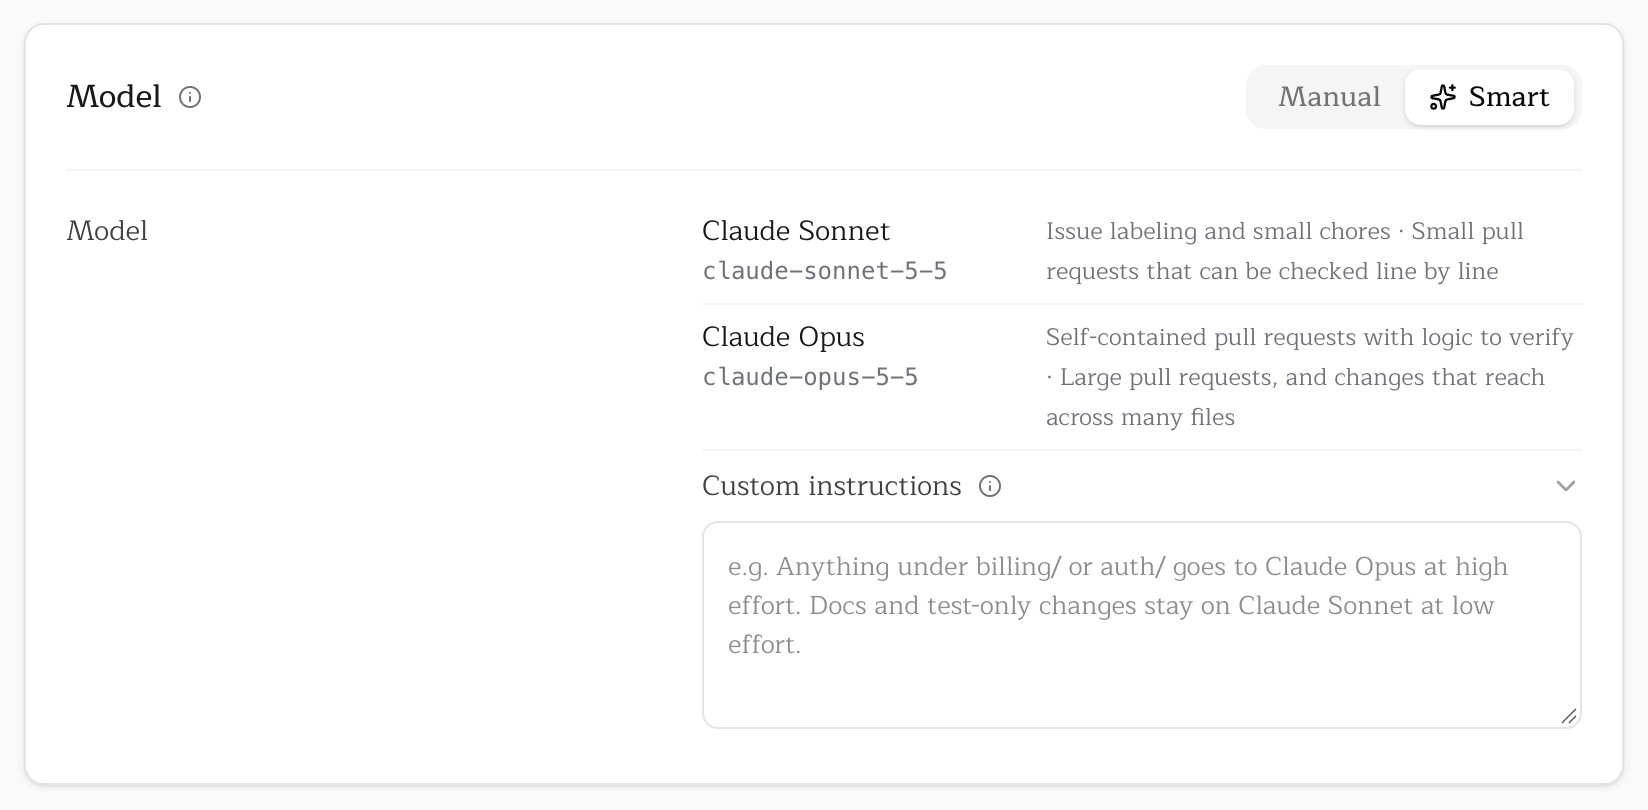
Smart runs cheap work on a provider's cheapest model and hard work on its frontier model. For pull request reviews, a model Pullfrog pays for reads the diff and picks one of four rungs.
| Rung | Work it gets |
| - | - |
| Minimal | Issue labeling, and reviews with no behavioral change |
| Light | New-issue enrichment, and small pull requests that can be checked line by line |
| Standard | Mentions, fixes and other tasks, and self-contained pull requests with logic to verify |
| Deep | Large pull requests, and changes that reach across many files |
Smart is included in the Pro, Organization and Enterprise [plans](/billing#plans) and in an organization's trial. Without one, the **Smart** tab shows a lock, and clicking it explains how Smart works and where to upgrade. A Smart setting saved before Pro lapsed is kept, and the card opens on **Manual**, showing the ladder's Standard rung, which is the model runs use meanwhile.
### Ladders
Each provider maps the rungs to its own models. While Smart is on, the **Provider** card lists only the providers in this table.
| Provider | Minimal | Light | Standard | Deep |
| - | - | - | - | - |
| Anthropic | Claude Sonnet | Claude Sonnet | Claude Opus | Claude Opus |
| OpenAI | GPT Luna | GPT Terra | GPT Sol | GPT Astra |
| Google | Gemini Flash | Gemini Flash | Gemini Pro | Gemini Pro |
| DeepSeek | DeepSeek Flash | DeepSeek Flash | DeepSeek Pro | DeepSeek Pro |
| xAI | Grok 4.3 | Grok 4.3 | Grok | Grok |
| Moonshot AI | Kimi K2 | Kimi K2 | Kimi K3 | Kimi K3 |
| OpenRouter | DeepSeek Flash | GPT Luna | GPT Sol | Claude Opus |
| OpenCode Zen | GPT Luna | GPT Luna | GPT Sol | Claude Opus |
| [Pullfrog Router](/billing#pullfrog-router) | DeepSeek Flash | GPT Luna | GPT Sol | Claude Opus |
On Pullfrog Router, Smart runs DeepSeek Flash for everything until a card is on file. A per-run [`--model` flag](/flags#model) overrides Smart, and [Pullfrog for OSS](#pullfrog-for-oss) repositories don't use it.
### Custom instructions
Under Smart, **Custom instructions** takes standing guidance for the pick: which paths or kinds of change deserve the top model or more effort, and which can stay on the cheapest rung. Changing the provider clears it. Lockfiles, snapshots, generated files and binary files are already left out when a diff is weighed. Guidance for the review itself belongs in **Standing instructions**.
 ## Pullfrog for OSS
Repositories in [Pullfrog for OSS](https://pullfrog.com/for-oss) have their model costs covered by Pullfrog, so the picker offers the set we fund:
| Model | Notes |
| - | - |
| **DeepSeek Flash** | Recommended, and the default |
| GPT Luna | OpenAI's cost-efficient tier |
| MiniMax M2 | |
| Muse Spark Contributor | Meta's discounted tier. Meta may train on the prompts and completions. |
A model outside this set falls back to the default, and the PR footer says so. The exception is a provider key stored **with Pullfrog**: the run then uses your key and your pick. A key that lives only in GitHub Actions secrets doesn't count, because the server can't see it when it decides. The same rule applies to a per-run [`--model` flag](/flags#model).
## Model resolution
When a run starts, Pullfrog takes the first model set in this order:
1. Per-run flag (`--model`)
2. Repository model in the console, or Smart's pick when the repository is set to Smart
3. Workflow input (`model:`)
4. Organization default in the console, or Smart's pick when the default is Smart
5. Auto-select: the best curated model your keys can reach, preferring each provider's top tier
6. OpenCode's own default
Specifiers use the [models.dev](https://models.dev) format (`anthropic/claude-opus-5-5`), and Pullfrog's aliases map onto them.
The model also decides which agent runs. An Anthropic model with Anthropic credentials runs on Claude Code, and everything else runs on OpenCode. Organizations opted in to the experimental [Codex CLI](https://developers.openai.com/codex/cli) agent run OpenAI models on Codex when a [Codex subscription](/codex-auth) or an `OPENAI_API_KEY` is present. Runs billed through Pullfrog Router or the OSS program always use OpenCode.
## Supported providers
| Provider | API key env var |
| - | - |
| Anthropic | `ANTHROPIC_API_KEY` (or a [Claude subscription](/claude-auth)) |
| OpenAI | `OPENAI_API_KEY` (or a [Codex subscription](/codex-auth)) |
| Google | `GOOGLE_GENERATIVE_AI_API_KEY` or `GEMINI_API_KEY` |
| xAI | `XAI_API_KEY` (or a [Grok subscription](/grok-auth)) |
| DeepSeek | `DEEPSEEK_API_KEY` |
| Moonshot AI | `MOONSHOT_API_KEY` |
| Meta | `META_MODEL_API_KEY`, from the [Meta Model API](https://dev.meta.ai), for Muse Spark |
| [Kimi Code](/kimi-code) | `KIMI_API_KEY`, from a Kimi membership rather than a Moonshot API balance |
| OpenCode | `OPENCODE_API_KEY`: one key for [Zen and Go](#opencode-zen-and-opencode-go), also required for the free Zen models |
| OpenRouter | `OPENROUTER_API_KEY` |
| Vercel AI Gateway | `AI_GATEWAY_API_KEY` |
| [Amazon Bedrock](/bedrock) | `AWS_BEARER_TOKEN_BEDROCK` (or `AWS_ACCESS_KEY_ID` + `AWS_SECRET_ACCESS_KEY`) + `AWS_REGION` + `BEDROCK_MODEL_ID` |
| [Google Vertex AI](/vertex) | `VERTEX_SERVICE_ACCOUNT_JSON` + `GOOGLE_CLOUD_PROJECT` + `VERTEX_LOCATION` + `VERTEX_MODEL_ID` |
| [Azure OpenAI](/azure) | `AZURE_RESOURCE_NAME` + `AZURE_API_KEY` + `AZURE_DEPLOYMENT` + `AZURE_CONTEXT` + `AZURE_MAX_OUTPUT` |
| [Custom › OpenAI-compatible](/openai-compatible) | `OPENAI_COMPATIBLE_BASE_URL` + `OPENAI_COMPATIBLE_API_KEY` + `OPENAI_COMPATIBLE_MODEL` + `OPENAI_COMPATIBLE_CONTEXT` + `OPENAI_COMPATIBLE_MAX_OUTPUT` |
## Custom providers
The table above lists the providers the console has a card for. Any other provider in the [models.dev](https://models.dev) catalog runs too, through [OpenCode](https://github.com/anomalyco/opencode): Groq, Mistral, Cerebras, Together, Fireworks and the rest switch on as soon as their API key is in the run's environment.
Set the account to **BYOK** in the **Providers** section of the **Billing** card first. On Pullfrog Router the server hands the run a Router credential before it starts, and it cannot see a key that lives only in GitHub Actions secrets.
Add it as a GitHub Actions secret, under the exact name that provider's [models.dev](https://models.dev) page declares.
The specifier must be one models.dev lists; the run checks it against the provider's catalog before starting. Non-secret settings some providers want, such as a region or an endpoint, go straight in `env:`.
```yaml theme={null}
- name: Run agent
uses: pullfrog/pullfrog@v0
with:
prompt: ${{ inputs.prompt }}
model: groq/llama-3.3-70b-versatile
env:
GROQ_API_KEY: ${{ secrets.GROQ_API_KEY }}
```
A model stored for the repository in the console beats the workflow's `model` input, so pick **Custom (set in workflow)**, or **Inherit from org** if your organization has a default. The job log confirms the specifier took:
```
» "groq/llama-3.3-70b-versatile" is not a curated alias — passing through as a raw model specifier
```
Use [OpenAI-compatible endpoints](/openai-compatible) instead when your provider isn't in the catalog, when you front several providers behind one gateway, or when you need a model ID the catalog doesn't carry.
## Routers
OpenRouter, OpenCode Zen, OpenCode Go and Vercel AI Gateway are providers like any other, with their own aliases (OpenRouter's "Claude Opus" is `openrouter/~anthropic/claude-opus-latest`). To pin an exact version instead of the rolling alias, set the `model` input to the full specifier:
```yaml theme={null}
with:
model: openrouter/anthropic/claude-sonnet-5
env:
OPENROUTER_API_KEY: ${{ secrets.OPENROUTER_API_KEY }}
```
### OpenCode Zen and OpenCode Go
[Zen](https://opencode.ai/zen) and [Go](https://opencode.ai/go) are two OpenCode plans behind one credential. Store `OPENCODE_API_KEY` once and both groups appear in the picker.
| Plan | Billing | Models |
| - | - | - |
| **OpenCode Zen** | Pay as you go | Claude, GPT, Gemini, Grok, Kimi, MiniMax, GLM, Qwen, Mistral, MiMo, LongCat, Step, Muse Spark |
| **OpenCode Go** | \$10/month, capped usage | GLM, Qwen, Kimi, MiniMax, MiMo, LongCat, Hy3, plus Grok and GPT Luna |
Most of the Go catalog is not served on Zen, so the two groups are different menus.
DeepSeek and Muse Spark are not on the Go menu. OpenCode gates them on a workspace opt-in that is off by default (China hosting for DeepSeek, data collection for Muse Spark), so a run without it refuses with a link to the setting. Turn the opt-in on in your OpenCode workspace and run them by full specifier, as below. DeepSeek needs no opt-in on any other route.
### Models the picker does not carry
The picker is a curated menu. Any other model either endpoint serves runs by its full [models.dev](https://models.dev) specifier:
```yaml theme={null}
with:
model: opencode-go/mimo-v2-omni
env:
OPENCODE_API_KEY: ${{ secrets.OPENCODE_API_KEY }}
```
Set the console model to **Custom (set in workflow)** so a stored pick does not beat the workflow input, as with [custom providers](#custom-providers).
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.