> ## Documentation Index
> Fetch the complete documentation index at: https://docs.pullfrog.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Azure OpenAI
> Run Pullfrog on OpenAI models deployed in your own Azure OpenAI resource.
Route Pullfrog's model calls through your own Azure OpenAI resource. Inference bills to your Azure subscription, so Azure credits and commitments apply.
Azure OpenAI is bring-your-own-key only. Pullfrog never proxies Azure traffic.
## Setup
In the Pullfrog console, pick the **Azure OpenAI** tile on the **Provider** card.
Click **Set up** on the tile and fill in the five values from the table below. Pullfrog injects them into every run, so `pullfrog.yml` needs no changes.
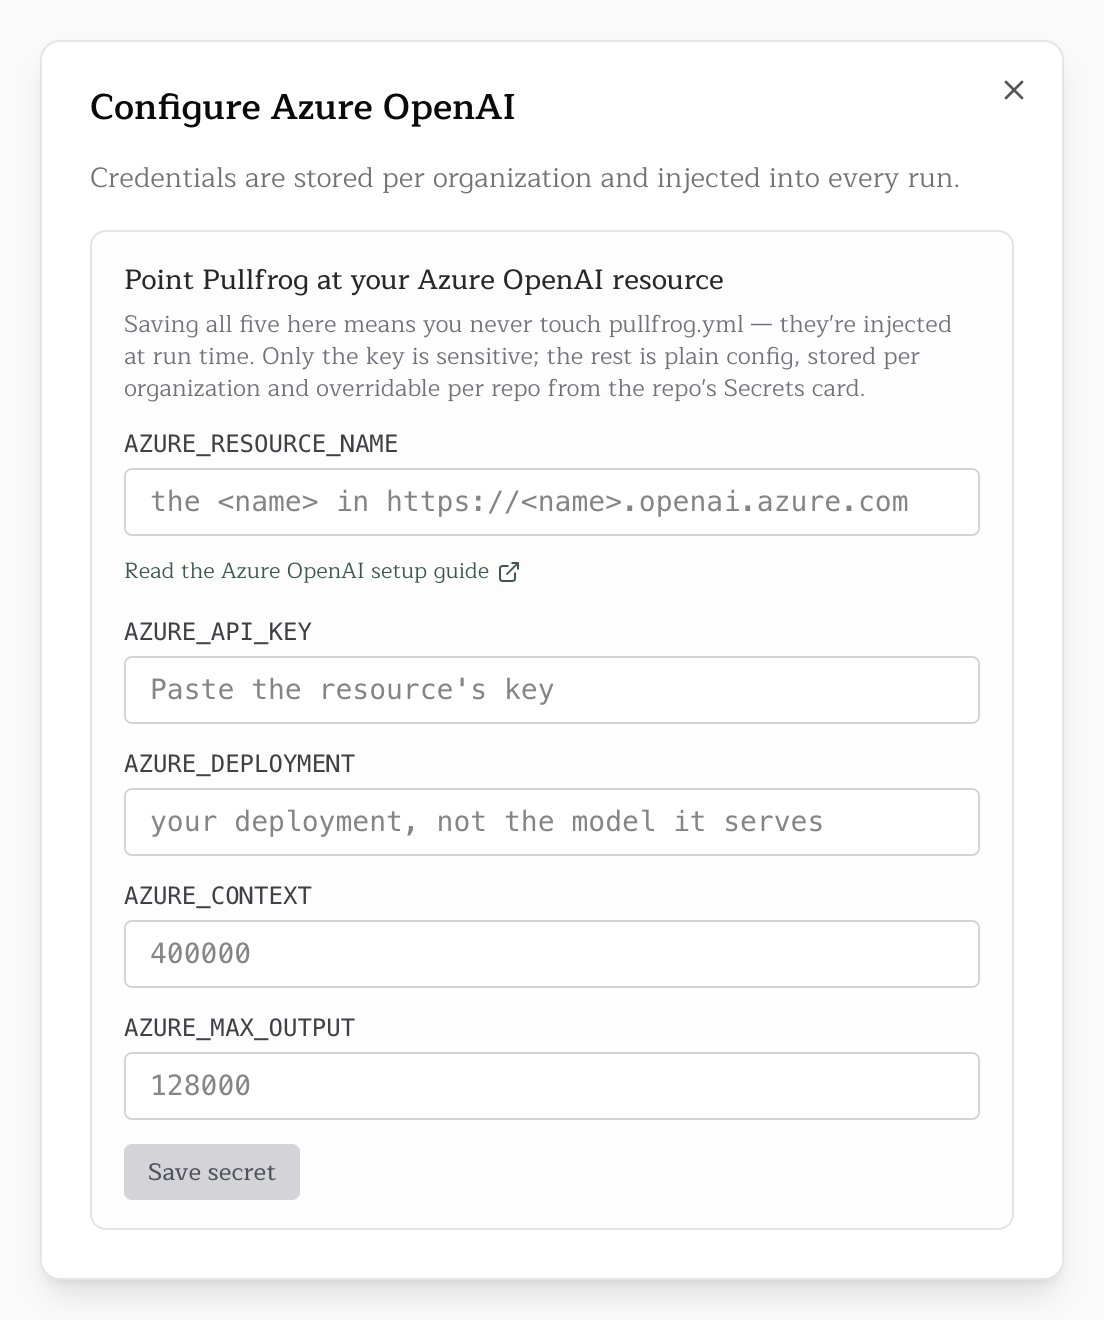 To keep them in the workflow instead, put `AZURE_API_KEY` in a GitHub Actions secret and the rest in the `env:` block of `.github/workflows/pullfrog.yml`:
```yaml theme={null}
env:
AZURE_RESOURCE_NAME: my-resource
AZURE_API_KEY: ${{ secrets.AZURE_API_KEY }}
AZURE_DEPLOYMENT: my-deployment
AZURE_CONTEXT: "400000"
AZURE_MAX_OUTPUT: "128000"
```
## Variables
| Name | Secret | Purpose |
| - | - | - |
| `AZURE_RESOURCE_NAME` | No | The `` in `https://.openai.azure.com`. |
| `AZURE_API_KEY` | Yes | A key for that resource. |
| `AZURE_DEPLOYMENT` | No | The deployment's name, which is not always the model's name. |
| `AZURE_CONTEXT` | No | Context window of the model behind the deployment, in tokens. |
| `AZURE_MAX_OUTPUT` | No | Maximum completion tokens that model accepts. |
| `AZURE_USE_CHAT_COMPLETIONS` | No | Optional. Set to `"true"` for a model that predates the Responses API. |
The first five are required. The two limits must be positive numbers, so `128k` is rejected. A value set in the workflow wins over a stored one.
On an account that pays through [Pullfrog Router](/billing#pullfrog-router), store the values in the Pullfrog console. Pullfrog decides how to fund a run before the runner starts, when GitHub Actions secrets are not visible to it, so a run whose key exists only there falls back to the Router's default model.
### Token limits
A deployment name carries no model metadata, so Pullfrog cannot look up the limits and needs you to declare them. Undeclared limits would break two things:
* **Completions are capped at 32000 tokens**, and a model with a smaller cap rejects every request.
* **Auto-compaction turns off.** Compaction keys off the context limit, so a long session grows until Azure refuses it.
Set `AZURE_CONTEXT` to the real window of the deployed model. A low value compacts earlier than needed; a high value delays compaction until Azure refuses the request.
### Reasoning effort
The [effort setting](/models#reasoning-effort) does not apply to Azure runs. A deployment name does not identify a model, so Pullfrog sends no effort level and the model's own default applies.
## Deployment name
Azure routes on the deployment name, not the model name. Set `AZURE_DEPLOYMENT` to the name given to the deployment, which defaults to the model's name but is often changed:
* Deployed `gpt-5` and kept the default name: `AZURE_DEPLOYMENT: gpt-5`
* Renamed the deployment `prod-reasoning`: `AZURE_DEPLOYMENT: prod-reasoning`
Find the name under **Deployments** in [Microsoft Foundry](https://ai.azure.com), or under **Model deployments** on the resource in the Azure portal.
Any OpenAI model the resource has deployed works. Non-OpenAI models on Azure, such as Anthropic, DeepSeek, Llama, Mistral and Phi, are [Foundry Models](https://learn.microsoft.com/en-us/azure/ai-foundry/foundry-models/) served from a different endpoint, which this integration cannot reach. Point [OpenAI-compatible endpoints](/openai-compatible) at the Foundry inference URL for those.
## Routing
Pullfrog sends requests to the resource's Responses endpoint, `/openai/v1/responses`, through OpenCode's `azure` provider. GPT-5-family models speak it as deployed. Older deployments such as `gpt-4` and `gpt-35-turbo` speak only Chat Completions; set `AZURE_USE_CHAT_COMPLETIONS: "true"` for them.
Pullfrog sends a static key and cannot refresh a Microsoft Entra ID token during a run. If your organization forbids resource keys, put a gateway that does the token exchange in front of the resource, and point [OpenAI-compatible endpoints](/openai-compatible) at the gateway.
## Troubleshooting
| Symptom | Fix |
| - | - |
| `AZURE_DEPLOYMENT env var is required when the model is set to "azure/byok"` | The repository uses Azure OpenAI, but no deployment name is stored or set in the workflow. |
| "Azure OpenAI selected but required configuration is missing" | The message names each missing value. Store it in the console or list it in the workflow `env:`; GitHub Actions passes only the secrets the workflow file names. |
| HTTP `404` from Azure | `AZURE_RESOURCE_NAME` does not match the endpoint hostname, or `AZURE_DEPLOYMENT` is not a deployment on that resource. A Foundry model also returns `404` here. |
| HTTP `401` from Azure | The key belongs to a different resource. Each resource has its own keys. |
| An error about the Responses API | The deployment serves a model that predates it. Set `AZURE_USE_CHAT_COMPLETIONS: "true"`. |
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.